 Now StreamingFounding Engineer at NeuraScribe AISep 2026
 New ReleaseRaftKV: Raft consensus from scratch, live in your browserSep 2026
 New Releasemini-vLLM: a small LLM inference engineSep 2026
 Award Winner1st of 150 teams at Cyber Cup 5.02025
 New CertificationIntroduction to Model Context Protocol2025
 New ArrivalAI Outfit Recommender2024
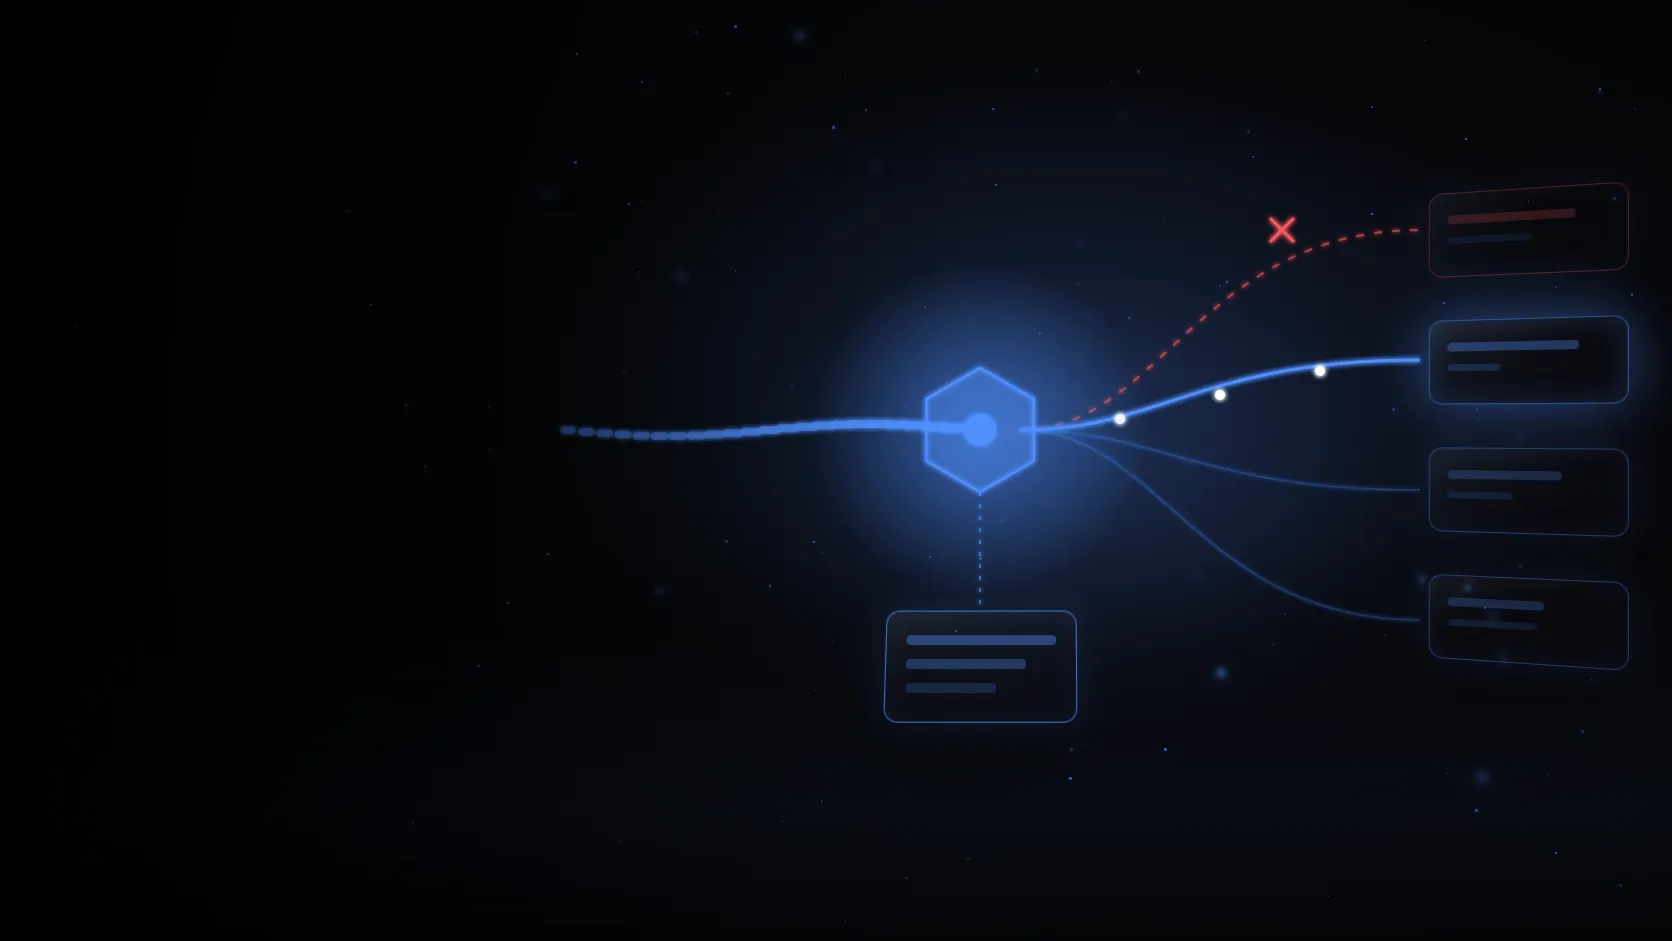
Architflix Original
ModelMux
One OpenAI-compatible API in front of many LLM providers. Every model name is a fallback chain, so a rate-limited or dead provider is skipped before your client sees a byte. Adds about 0.14 ms at the median and recovered every recoverable request across five fault scenarios.
Overview
ModelMux is a single-binary Go gateway by Archit Jain that puts one OpenAI-compatible API in front of many LLM providers, with fallback chains, circuit breakers, exact and semantic caching, and per-tenant keys, rate limits and budgets, adding about 0.14 ms at the median.
Season 1 · The Build
5 episodesOne OpenAI-compatible API in front of many LLM providers. Every model name is a fallback chain, so a rate-limited or dead provider is skipped before your client sees a byte. Adds about 0.14 ms at the median and recovered every recoverable request across five fault scenarios.
Built with Go, Prometheus, Docker, k6, Ollama.
Any OpenAI SDK can point at ModelMux. A model name resolves to an ordered chain of providers (OpenAI-compatible APIs such as OpenAI, Groq, Gemini, Ollama and vLLM, plus two-way Anthropic translation including streaming and tool calls), and a request moves down the chain on rate limits, server errors and timeouts. Streaming is the hard case: a stream commits to a provider only when its first chunk arrives, so failures before the first byte fall back invisibly, while a failure mid-stream ends with an in-band error and is never cached. A per-provider circuit breaker stops sending traffic to a dead provider, and only a designated probe request can close it again. Per-tenant API keys (stored hashed), model allow-lists, rate limits and monthly token budgets reserved up front control admission, and every admitted request emits a usage event and Prometheus metrics. An exact cache answers repeated requests, and an opt-in semantic cache answers paraphrases, guarded by an entity check because embeddings treat "hotels in Udaipur" and "hotels in Munnar" as near-identical. The benchmarks are honest about that trade-off: the semantic cache was tuned on one set of question pairs and evaluated on a held-out set, where it safely served 14.4% of paraphrases at a 0.4% wrong-answer rate, so it ships off by default. Against a 50 ms stub, the gateway adds 0.14 ms at the median and 0.58 ms at p99 at about 2,000 requests per second; in all five recoverable fault scenarios every recoverable request was recovered, and with the breaker on, a dead provider received only 23-32 of 2,000 requests. Built by Archit with Claude as the AI coding assistant.
- OpenAI-compatible endpoint in front of OpenAI, Groq, Gemini, Ollama and vLLM, plus two-way Anthropic translation with streaming and tool calls
- Fallback chains with a first-byte timeout; streams commit to a provider only after the first chunk
- Per-provider circuit breaker that only a designated probe can close; client disconnects don't count as failures
- Exact cache plus an opt-in semantic cache with an entity guard against swapped names and places
- Hashed per-tenant keys, model allow-lists, rate limits and monthly token budgets reserved up front
- Usage events, Prometheus metrics, and a playground with simulated provider outages
- A single Go binary on net/http with no framework; Docker image and a Render blueprint
Every project hits walls. Here's what nearly broke ModelMux — and how it shipped anyway.
- Streaming fallback: retry only before the first chunk, end mid-stream failures with an in-band error, never cache a broken stream
- Semantic caching is risky: embeddings rate swapped entities as near-duplicates, so a lexical guard was added, and re-evaluating on held-out pairs cut the headline from 21.4% to about 14% of paraphrases
- Circuit-breaker correctness under concurrency: one probe at a time, and client cancellations kept out of the failure count
- Translating the Anthropic API both ways: system-prompt placement, merging tool results, and re-cutting stream events
- Making cache lookups fast enough to skip an approximate index: unrolling the dot product cut a 2,000-entry scan from 2.55 ms to 0.99 ms
Every build leaves residue. The takeaways from ModelMux that carry forward.
- A gateway's real job is failure handling; the happy path is just a proxy
- Evaluate caches on held-out data: the honest number (about 14%) was a third lower than the first one, which is why the feature ships off by default
- Measure overhead against a stub, not a real provider, or network noise swamps the result
- Known limits: all state is in memory (not shared across replicas), token counts are estimated when providers don't report them, and the numbers come from one machine